
Tutorial : Multi-Agent interactions with Autogen and Gemini — Part 4: Using local LLMs
In this series, we have seen how to use the Autogen framework to create autonomous multi-agents that can communicate with each other. We also introduced a human element in the process, where a human can review the output of the Autonomous Agent and then take some decision based on that.
The series:
- Part 1 : Introduction and Getting Started
- Part 2 : Terminating Conversations
- Part 3 : Human in the Loop : How to introduce manual human intervention
- Part 4 : Using local LLM’s (this post)
- Part 5 : Using AgentOps : Monitoring, Metrics for your Agent
In our code samples so far, we have been using the Google Gemini models that are hosted online for the LLM. What if you would like to replace those by an open source model that you would like to run locally (yes — on your machine). In this part, we are going to see how to use Ollama, that helps us run one or more models where we want (in our case locally) and configure our agents to use that.
Installing Ollama
The installation steps are straightforward and involves downloading the Ollama environment locally and then pulling one or more models that can be run. Let’s go through the steps:
Download and install Ollama
Simply visit and https://ollama.com/ and download the application for your environment. I have a MacOS machine and have downloaded the Mac distribution. Since running a local LLM requires a good amount of compute+memory, ensure that your machine specifications are good enough to run Ollama and atleast one of the models.
Once installed, you will find that the Ollama application is available and you can run it via a terminal/command prompt as given under
$ ollama
Usage:
  ollama [flags]
  ollama [command]

Available Commands:
  serve       Start ollama
  create      Create a model from a Modelfile
  show        Show information for a model
  run         Run a model
  stop        Stop a running model
  pull        Pull a model from a registry
  push        Push a model to a registry
  list        List models
  ps          List running models
  cp          Copy a model
  rm          Remove a model
  help        Help about any command

Flags:
  -h, --help      help for ollama
  -v, --version   Show version information

Use "ollama [command] --help" for more information about a command.
This is expected since we have not yet downloaded (pulled) any model. If you do a $ ollama ls , you will not get any models listed.
Pull a model locally
Ollama supports a wide range of models. You can choose which model to download as per your requirements. Let’s go with one of the Gemma models, as we see below. I went with gemma.
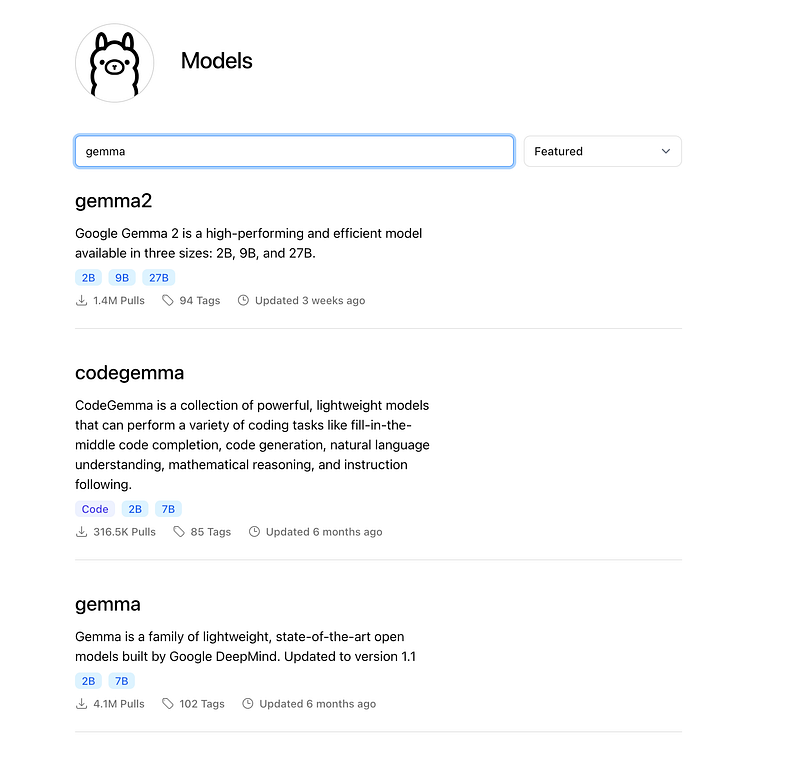
When you click on gemma , you will see the details for that model and instructions on how to download and use the model.
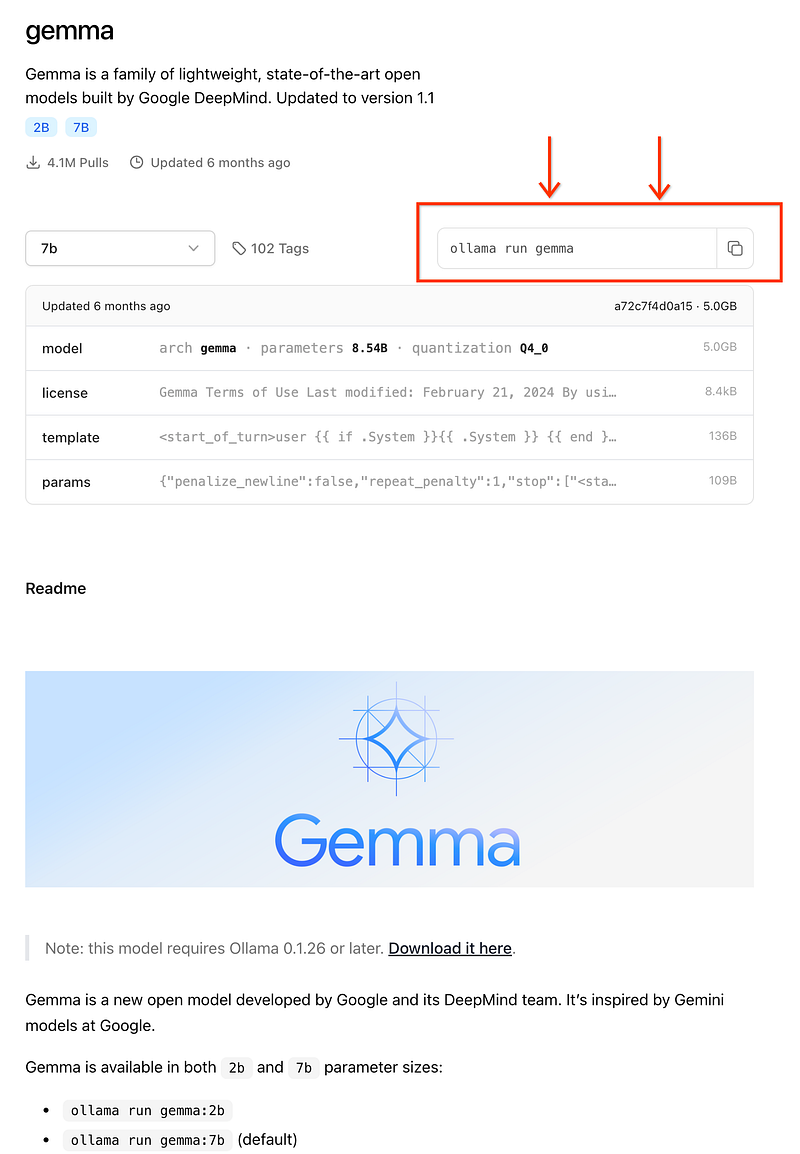
In your terminal, give either the command ollama pull gemma or ollama run gemma. The later will not just pull the model (be aware, it could take time since its a few GBs and your internet speed will decide how long its going to take) but also run an interactive command line shell, where you can talk to the model.
Talk to the model
Validate that the entire process was done correctly, as follows:
Launch the Ollama interactive shell with the specific model that you downloaded:
$ ollama run gemmaThis will bring up the interactive shell, where you can try out a few prompts:
$ ollama run gemma
>>> Tell me a famous quote from Socrates
"I know that I am intelligent because I know that I know nothing." - Socrates

>>> /bye
Ensure that this is indeed working because it is important to have this setup correctly.
Test the Ollama API via curl
Let’s understand the API endpoint that is exposed by Ollama environment and invoke our model with a prompt via curl. This will help us create a mental model of what it means to configure inside of our application.
Assuming that you have the curl utility on your machine or any of the API clients (I like Bruno), we can hit the Ollama API endpoint for our model as given below:
curl http://localhost:11434/api/generate -d '{
   "model": "gemma",
   "prompt":"Give me a famous quote from Aristotle?",
   "stream": false
 }'
Notice that we are providing the following parameters:
- model : This is the model that we have pulled/downloaded into Ollama. In our case it is gemma, but feel free to replace it with a model that you have opted to download.
- prompt : This is the prompt that I wish to send to the model.
- stream: By default this is
true. I have chosenfalse.
This results in the following output. Make sure Ollama is running.
{
 "model":"gemma",
 "created_at":"2024-10-10T10:32:12.226589Z",
 "response":"\"Happiness is the ultimate end of life, and its pursuit is the highest of all aims.\"",
 "done":true,
 "done_reason":"stop",
 "context":[968,2997,235298,559,235298,15508,235313,1645,108,23136,682,476,10964,14232,774,70676,181537,615,235298,559,235298,15508,235313,108,235322,2997,235298,559,235298,15508,235313,2516,108,235281,122107,603,573,17027,1580,576,1913,235269,578,1277,36936,603,573,9393,576,832,22346,1464],
 "total_duration":5047128125,
 "load_duration":40100625,
 "prompt_eval_count":34,
 "prompt_eval_duration":4252836000,
 "eval_count":20,
 "eval_duration":750594000
}
Do refer to the API documentation for more endpoints and multiple other parameters that you can provide while working with the model.
Using local LLMs in Autogen
We are now at the final stage and which is all about modifying our code to use the local LLMs that we have configured. I am going to use the same application that we utilized in Part 3, where there is a human and autonomous agent interaction. The human asks for a quote, the agent returns back one and the human reviews it, says ok or asks for another quote.
All we need to do now is to modify the Autonomous Agent configuration i.e. while instanting the ConversableAgent class to use the local LLM list instead of the Google Gemini list that we had configured earlier.
The entire code listing is shown below:
Notice in the code that we are configuring a local list of the LLM and the endpoint in the config_list_local_llm variable. The rest of the code remains the same.
If you run the application, its as before, except that the LLM is now served locally.
Human (to quote_agent):

Provide me a quote that is from one of the Greek philosophers on Life

--------------------------------------------------------------------------------
quote_agent (to Human):

"Man is not what he eats, but what he thinks." - Epictetus

--------------------------------------------------------------------------------
Replying as Human. Provide feedback to quote_agent. Press enter to skip and use auto-reply, or type 'exit' to end the conversation:

>>>>>>>> NO HUMAN INPUT RECEIVED.

>>>>>>>> USING AUTO REPLY...
Human (to quote_agent):

Give me another quote

--------------------------------------------------------------------------------
quote_agent (to Human):

"Happiness is not a destination, but a way of life." - Buddha

--------------------------------------------------------------------------------
Replying as Human. Provide feedback to quote_agent. Press enter to skip and use auto-reply, or type 'exit' to end the conversation: ok
Human (to quote_agent):

ok

--------------------------------------------------------------------------------
You can experiment with other prompts and local models available through Ollama that meet your requirements.
Conclusion
This concludes Part 4 of the series, where we saw how we can configure a local LLM via Ollama and use that in the Autogen framework. In the next parts, I will look at Agent Ops and then cover a few different conversational patterns. Stay Tuned.


