
Introduction to Data Structures and Algorithms
Unraveling Data Structures and Algorithms: A Beginner’s Guide for Aspiring Developers.
Are you interested in learning more about Data Structures and Algorithms? Here is what you need to know to get started.
LEARNING OBJECTIVES
Understanding the concepts of Data Structures and Algorithms.
Recognizing Data Structures as tools for organizing and storing data efficiently.
Exploring various types of data for diverse computational tasks.
Introduction
Data structures in computer science and software development are crucial for effectively organizing and managing data. Whether you’re a beginner or an experienced programmer, understanding different data structures and their applications is essential for writing efficient and scalable code.
In this series, we will delve into the world of computer science and explore the concept of Data Structures and Algorithms. We will explore some of the most common data structures, including defining what they are, identifying some use cases, explaining the operations we can conduct on them, and exploring their various implementations.
Importance of Data Structures and Algorithm (DSA)
In today’s data-centric world, there is a need for efficient data storage and access, which makes DSA crucial. One practical example of the importance of DSA is Google’s mechanism of indexing and retrieving web pages quickly and accurately. By employing efficient search algorithms, users can find information within milliseconds amongst massive amounts of data.
When traveling from point A to point B, GPS navigation systems rely on data structures and algorithms to calculate the shortest and fastest routes. Popular graph algorithms like Dijkstra’s algorithm help determine optimal paths by considering traffic conditions and road networks.
Various healthcare companies rely on DSA for electronic health record systems to store and retrieve patient information efficiently. Banks and other financial institutions rely on data structures and algorithms for transaction processing, portfolio optimization, and other tasks.
Whether you are a software engineer or a computer scientist. If you intend to build and design complex systems for data storage and processing, understanding the concepts behind data structures and algorithms is crucial
What exactly are Data Structures?
Data structure describes a systematic approach to organizing, storing, and retrieving data in computer science. They provide a means to collect and store data in a way that optimizes specific operations such as searching, sorting, and accessing data. Data are typically stored in a database or a computer’s memory.
Algorithms are step-wise instructions detailing how to solve a problem on a data structure within a finite set of time — meaning an algorithm must be terminated. These instructions are designed to effectively manipulate data stored on a particular data structure.
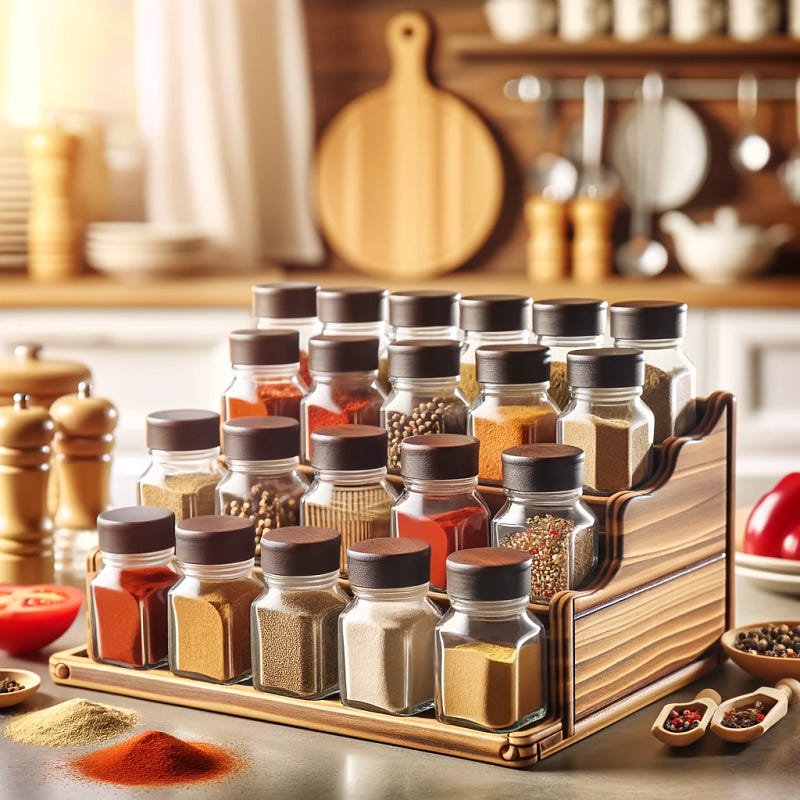
Imagine you are cooking a meal, something I often do. In the cabinet above the stove, I bought a spice jar to organize my spices in a certain way. I have them arranged so that I can easily access my cayenne and crushed peppers, which I keep separate from the salt and dry rubs, and if I need the dry herbs, I know exactly where to reach for them. I did it this way to solve the problem of searching the whole spices cabinet when I needed turmeric.
In this trivial example, the spice jar or rack and the mechanism I used to arrange my spices represent a data structure. I used an algorithm called “search” to find bay leaves, which are crucial to solving the “Jollof rice” problem.
Choosing the proper data structure for a specific problem can significantly impact the performance and scalability of an application. Efficiently organized data (Data structures) helps us design practical solutions to manipulate said data (Algorithms), leading to better problem-solving and decision-making.
Data Types
Before we go further, discussing the different data types in computer science is essential. It is important to understand the type of data we intend to store within our data structures. Data are typically categorized into primitive and non-primitive types.
Primitive Data Types
The standard primitive data types in computer science include the following:
- INTEGER type — whole numbers, positive or negative, without fractional and decimal parts. e.g., 12, 34, -67.
- REAL type — like integers, they are whole numbers that can be positive or negative but represent floating and decimal numbers. e.g., -0.7, 2.14.
- CHAR type — represents single characters like alphabets in the English language, symbols, and digits enclosed in single quotes. e.g., ‘@,’ ‘C,’ ‘y’.
- BOOLEAN type — are binary values that can be either true or false or the result of logical operations such as comparison.
int number = 123;
double decimalValue = 3.14;
char myCharacter = 'd';
bool shoudYouFollowMeAndLikeThisArticle= true;
int number = 456;
double floatValue = 1.1;
char charValue = 'D';
bool DoYouHateComputerScience= false;Non-Primitive Data Types
Non-primitive data types are more complex data types built upon primitive data types. A good example is the String data type built by a collection of the Char data type. In most high-level programming languages, a string is considered an array of Char-type values because each character in the string can be accessed and manipulated
# A string data type
my_name = 'Mark'

# Accessing a character from the string
first_letter = my_name[:1] # 'M'
The non-primitive data types can be further divided into:
- linear (Arrays, Stacks, Queues, and LinkedList ) and
- non-linear (Graphs, Trees, and Trie) types.
We will explore some of these data structures in a later series.
In computer science, you may encounter various classifications of data structures. One such categorization is elementary data structures, which are the basic physical data structures like arrays, hashtables, and linkedlist. On the other hand, abstract data structures (ADS) are typically built on an elementary data structure and are defined by the operations they perform.
One example of an ADS is a priority queue implemented using a heap data structure. This structure assigns a priority to the stored data and processes the data with the highest priority first. Another common ADS is the stack, which can be implemented using an array or linked list. We will discuss more ADS in later episodes of this series.
Conclusion
In this chapter, we explored the basics of Data Structures and Algorithms (DSAs), including the various data types and how they’re categorized. With this foundation, we will be taking a deeper dive into the realm of Algorithms and Complexity Analysis in the next chapter, where we’ll journey through how to efficiently analyze the complexity of an algorithm.


